AI-agent platform startup · 2026
A GTM engineering stack, built solo
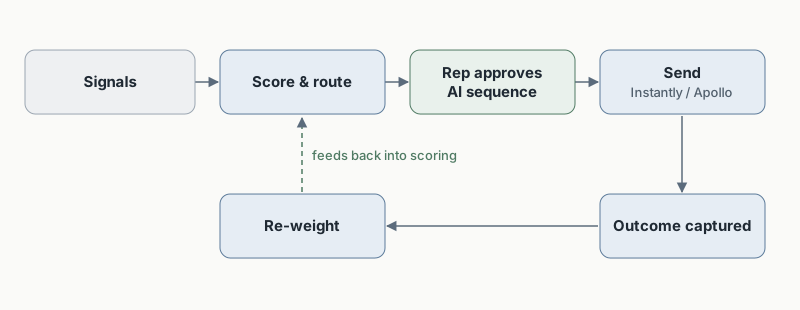
Signals feed a scoring model, the model deals accounts to rep queues, and reps approve AI-written sequences before anything sends.
~1,950 commits across 23 repos in ~4 months
The problem
The company had no GTM engineering layer. Reps picked accounts by feel. Signals lived in different tools, and nobody could say which accounts deserved attention this week or why. I was the only person building it.
What I built
One stack on one warehouse, in about four months.
- Signal detectors. Five live: leadership change, AI hiring, manual-process hiring, acquisitions and AI mandates. The leadership-change detector raised 84 alerts on its first live run. The manual-process hiring detector passed 57 of 60 validation checks.
- Account scoring. Version 1 seeded 5,582 accounts, 3,837 of them scoreable, with identity collapsing and score decay. A weekly sweep now covers about 7,000 accounts.
- Plays. Grew from 2 to 12, each with versioned seat rules and a guard test.
- Rep queue app. Accounts are dealt round-robin. Reps review a 4-email sequence and approve it, or swap the prospect. It went from a pilot page to v1.67 in six weeks, about 70 releases. A stop-everywhere sync halts a contact across every rep’s campaigns and sequences in about 4 seconds.
- Reply reader and outcome tracking. The classifier agreed with 158 of 160 test replies. Outcome tracking logged 3,033 outcomes on its first run.
Design decisions
- Rules before AI. Scoring, routing and seat rules are deterministic. AI writes the copy, and a person approves it.
- Approve-and-send lives inside the rep’s queue, on mobile too. Adoption comes before any other metric.
- I moved scheduled jobs to Supabase pg_cron after finding GitHub cron was dropping about 80% of runs.
- Model changes are forecast first. The live recount after a scoring cutover matched the prediction. No open card was lost.
- Half of accounts route to new message writers so the impact of new copy can be measured against the old.
Result
The alpha is live for two reps. It closes the loop from signal to outcome, so the scoring can be re-weighted from real results instead of opinion.